



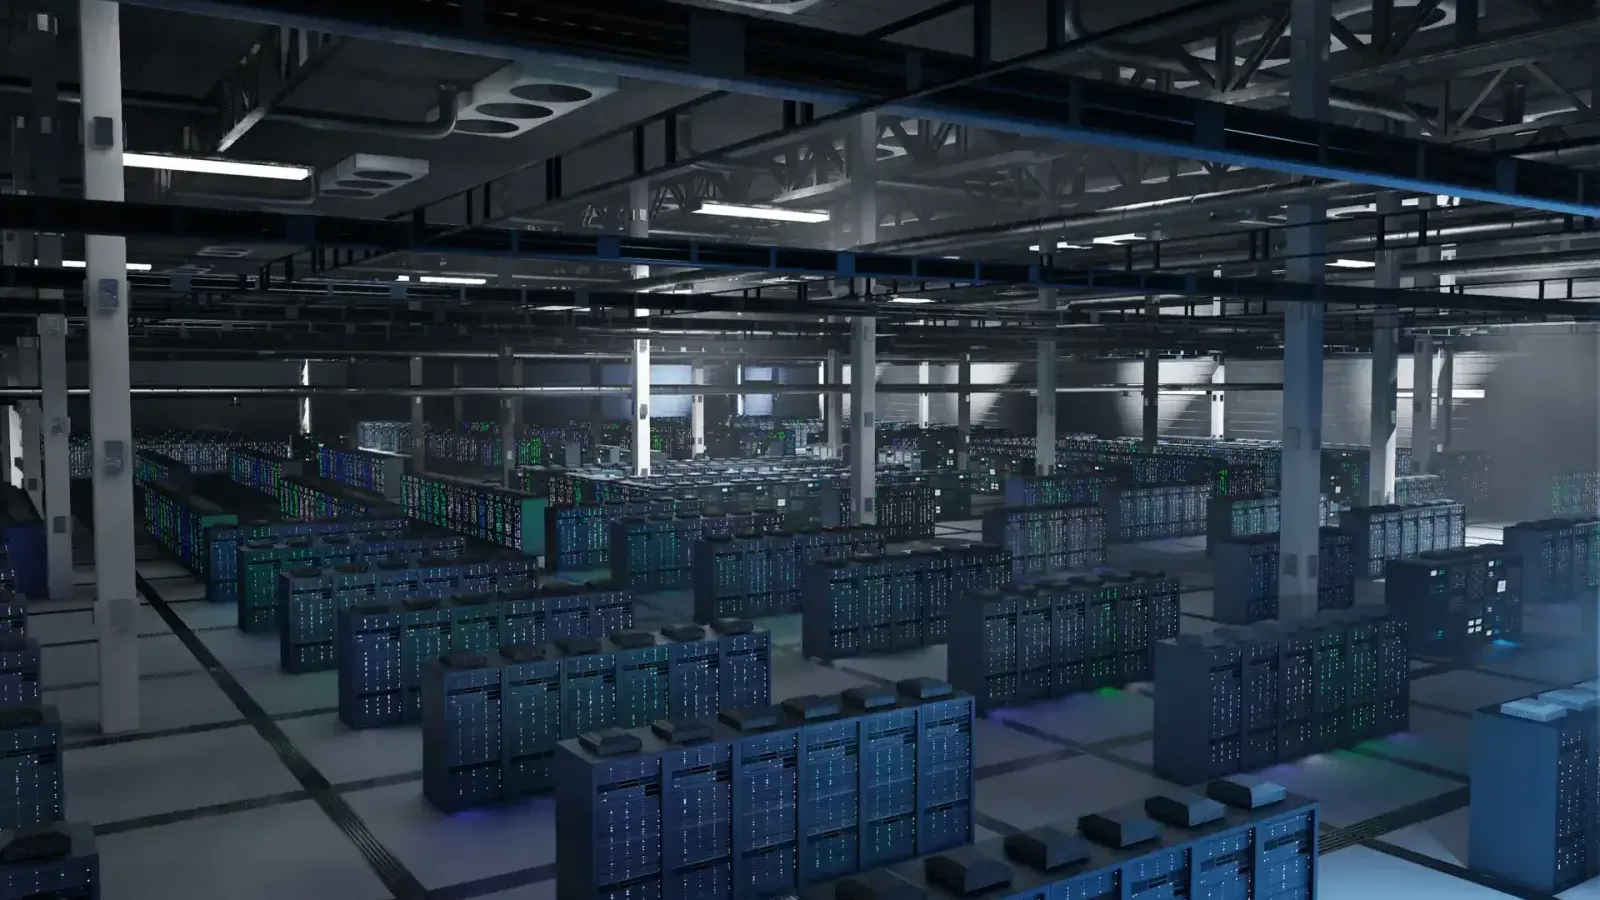
Genomic Data Storage and Pipelines for Precision Medicine
Raw reads, alignments and variant files pile up with every sample, and retention, copies and re-analysis multiply them. Agnotic Technologies builds genomic storage and pipelines to your program's requirements.
Last reviewed by the Agnotic Technologies engineering team
How much storage does a precision medicine program need?
A precision medicine program needs storage for the raw reads, alignments and variant files it keeps per sample, multiplied by every copy it holds and every year it retains them. Agnotic Technologies builds genomic data pipelines and tiered storage to each program's file sizes and retention policy, with recent runs on fast storage and older data archived.
Where does genomic storage go wrong?
Storage plans fail when they are built on someone else's file sizes or forget a copy.
Raw reads and alignments dominate
Raw reads and alignments hold every read, while a variant file holds only the calls. Whether you keep or delete the first two moves the total more than anything else.
Retention rules per file type
CLIA sets retention for test records and reports, and state rules may add more. Which genomic files fall under each rule is a laboratory decision the storage design has to follow.
Copies multiply the total
Backups, disaster recovery replicas, a second region and de-identified research copies are each another full copy of the files they include.
Re-analysis needs old data quickly
When clinicians or researchers ask for re-analysis of older samples, archive retrieval time decides how long they wait.
Format and pipeline changes shift sizes
Moving alignments from BAM to CRAM changes the size per sample, and a new sequencer or pipeline does the same. Plans built on old sizes drift.
Patient-linked files need safeguards
Genomic files linked to a patient are electronic protected health information and need the same access control, encryption and backup as the rest of the record.
What do we build for genomic data?
Agnotic Technologies builds genomic storage and pipelines to your requirements: your assays, file types, retention policy and the cloud or on-premises platform you choose.
Pipeline output management
Pipelines that register FASTQ, BAM or CRAM, and VCF outputs per sample and run, with checksums and the metadata needed to find each file later.
Hot and archive storage tiers
Lifecycle rules that keep recent runs and active re-analysis on fast storage and move older files to an archive tier.
Retention and deletion policies
Retention set per file type and test type, with scheduled deletion that leaves a record of what was removed and when.
Backup and replication
Retrievable exact copies of patient-linked data, as the HIPAA Security Rule contingency plan standard requires, with the number of copies and regions you choose.
Access controls and audit logs
Role-based access to genomic files, encryption at rest and in transit, and logs of who read or downloaded each file.
De-identified research copies
Pipelines that remove identifiers and publish a separate research or AI copy, tracked so it counts in the storage plan.
Results delivery to the EHR
Integration that carries variant results to the EHR as FHIR Genomics Reporting data, described on our precision medicine data integration page.
Storage growth reporting
Reports on terabytes per year by assay and file type, so growth and tier moves are visible before capacity runs out.
Which files does each sample produce?
Sizes differ by sequencer, depth, compression and pipeline, so a storage plan should use sizes measured from your own runs.
| File type | Format | What it holds | Why you might keep it |
|---|---|---|---|
| Raw reads | FASTQ, or unaligned BAM or CRAM | Every read with its base quality scores | Re-analysis with a newer pipeline from the start |
| Alignments | BAM or CRAM, with an index | Reads placed against a reference genome | Variant review, re-calling and troubleshooting |
| Variants | VCF or BCF | Called variants with genotypes and quality values | Interpretation, reporting and research queries |
How do you size genomic storage?
Take the median size of each file type from recent runs, per test type.
Decide which file types your policy keeps, for example whether raw reads are deleted once alignments are verified.
Set the retention period per file type and count every copy: the primary, each backup and each replica.
Decide the share of stored data that stays in hot storage, such as recent runs or samples under active re-analysis.
What drives genomic storage up?
- Re-analysis policy: raw reads and alignments hold every read while a variant file holds only the calls, so keeping or deleting the first two moves the total most.
- Retention rule: the years you keep each file type, set by your laboratory's records policy and the rules it follows.
- Replication: every copy for backup, disaster recovery or a second region multiplies the total.
- De-identification copies: a research or AI copy with identifiers removed is another full copy of the files it includes.
- Format choice: storing alignments as CRAM rather than BAM changes the alignment size per sample, so measure again after a format change.
- Working files: intermediate files, logs, QC reports and reference genomes take space beyond the three main file types.
How should storage be planned over time?
Plan growth from the yearly total and capacity from the total at the end of the retention period. After that point, deletions balance new data and the total stops growing, as long as volumes stay flat.
Use the hot and archive split to decide which data sits on fast storage for analysis and which moves to an archive tier with slower retrieval. Retrieval time matters if clinicians or researchers ask for re-analysis of older samples.
Design storage, backup and access controls together. Files linked to a patient need the same safeguards as the rest of the record.
Which standards and rules shape genomic data storage?
Short facts we design genomic storage around, each linked to its primary source.
The SAM v1 specification defines the SAM (Sequence Alignment/Map) format, its binary equivalent BAM and the BAI index format, and the HTS specifications are maintained by the GA4GH Large Scale Genomics work stream.
Source: HTS format specifications (GA4GH)The HTS specifications recommend storing unaligned sequence data in SAM, BAM or CRAM with the unmapped flag set, and note that FASTQ has no formal definition.
Source: HTS format specifications (GA4GH)Under CLIA, 42 CFR 493.1105 requires a laboratory to retain or be able to retrieve a copy of each test report for at least 2 years after reporting, and pathology test reports for at least 10 years.
Source: 42 CFR 493.1105 (eCFR)The HIPAA Security Rule's contingency plan standard requires a data backup plan: procedures to create and maintain retrievable exact copies of electronic protected health information.
Source: 45 CFR 164.308(a)(7) (eCFR)The HIPAA Security Rule requires administrative, physical and technical safeguards for electronic protected health information.
Source: 45 CFR Part 164 Subpart C (eCFR)
Trusted by global innovators











Which standards does Agnotic build healthcare software against?
HIPAA
Health Insurance Portability and Accountability Act
Protect PHI with privacy-first architecture, encrypted storage and transmission, strict access controls, and traceable audit logs.
GDPR
General Data Protection Regulation
Implement lawful consent flows, data minimization, retention controls, and secure processing for sensitive health data.
FHIR
Fast Healthcare Interoperability Resources
Enable standardized health data exchange across apps, care teams, and systems through standards-based FHIR APIs.
HL7
Health Level Seven International
Support enterprise-grade interoperability with HL7-based integrations for records, events, and clinical messaging workflows.
HITRUST
Health Information Trust Alliance
Align security programs to healthcare-specific control and risk management practices trusted by providers and ecosystem partners.
HITECH
Health Information Technology for Economic and Clinical Health Act
Design with breach notification readiness, digital record safeguards, and operational controls that support regulated care programs.
SaMD
FDA Software as a Medical Device
Plan software quality, traceability, and documentation pathways for products that may require SaMD review and submission.
MDR (EU)
Medical Device Regulation (European Union)
Prepare EU market-ready processes for risk classification, evidence tracking, and lifecycle governance under MDR expectations.
SAMHSA
Substance Abuse and Mental Health Services Administration
Apply confidentiality controls and consent-aware sharing models for behavioral and mental health data experiences.
Where should you go next?
- Precision medicine data integrationHow genomic results reach the EHR as FHIR Genomics Reporting data.
- Cloud FHIR storesManaged FHIR stores for clinical and genomic results.
- Laboratory information system developmentSample tracking, results and lab workflows.
- Cloud consulting servicesLanding zones, storage tiers and cost controls.
- Data warehouse storageHow raw and compressed data grow in an analytics warehouse year by year.
- PHI data securityEncryption, tokenization and access control for patient data.